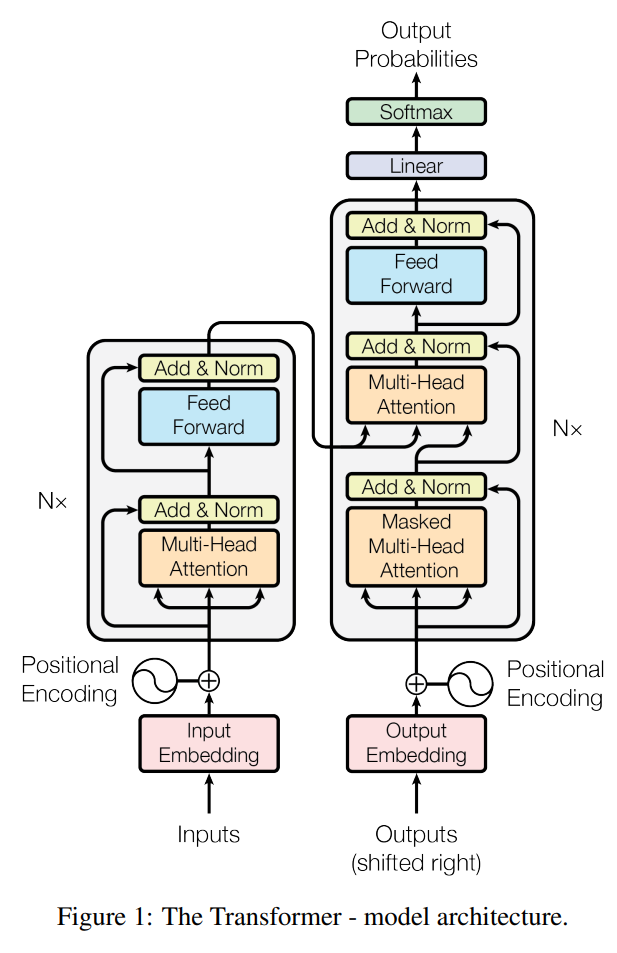
Transformer
The Transformer architecture, developed by researchers at Google Brain in 2017, is a groundbreaking deep learning model primarily used for natural language processing tasks. It was introduced in the paper “Attention Is All You Need” by Vaswani et al. The Transformer model revolutionized the field of NLP by introducing the concept of self-attention mechanisms and dispensing with the need for traditional recurrent neural networks (RNNs) or convolutional neural networks (CNNs).
The key innovation in the Transformer architecture is the self-attention mechanism, which allows the model to weigh the importance of different words in a given context. Which lay the foundation for the development of future GPT model.
Transformers consist of an encoder-decoder structure, here is the link that better explain the structure.