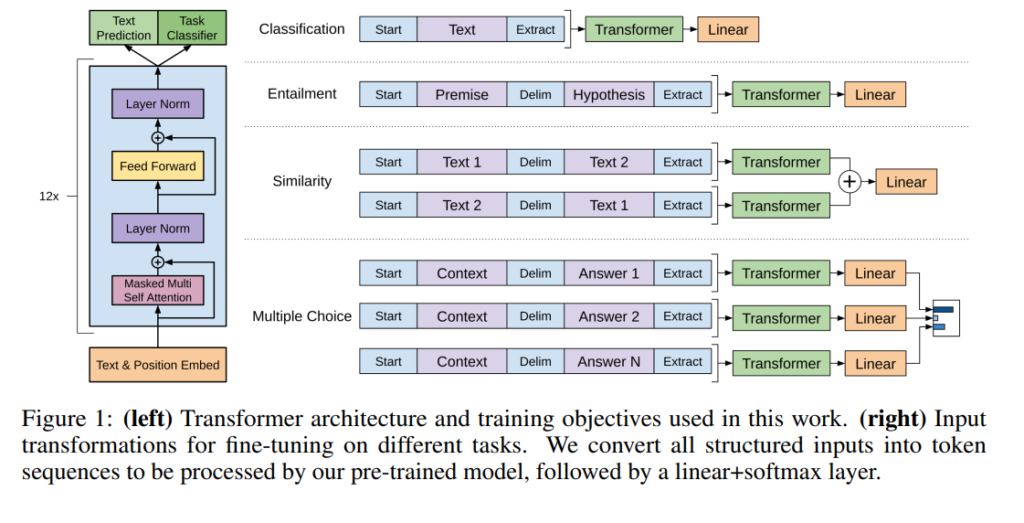
The first model in the series, GPT-1 was a smaller-scale model focused on proof-of-concept and early experimentation. Released in June 2018.
It is a large language model (LLM) with 117 million parameters trained on a dataset of about 8 million web pages.
Instead of using whole Transformer architecture, GPT only adopt the Decoder structure of the transformer, especially the Mask Multi-Head Attention mechanism, as it is a unidirectional model designed for generating text.
Other two mechanics are Pre-training and Fine-tuning mentioned at homepage, click the link down below to refer to original paper.